Combine many same-structure CSV exports into one file — headers matched once, types kept, a source column, and a count that reconciles.
Ash RaiTechnical Product Manager, Data & Engineering
6 min read
Quick answer — how to merge CSV files
On a Mac or Linux terminal, awk 'FNR>1 || NR==1' *.csv > combined.csv stacks every file and keeps one header (it assumes identical headers, column order, and encoding with one physical line per record, and is not safe for multiline quoted fields). In Excel, Data → Get Data → From Folder appends them and re-runs on refresh. To do it in the browser with no install — and get a column recording which file each row came from plus a count you can reconcile — upload the CSVs to an AI data analyst and ask it to combine them. All three stack the rows; none of them match on a key, which is a different job.
You have a stack of CSV exports with the same columns — one per week, per store, per export — and you want them in a single file. There are three good ways, and the right one depends on whether you can run a command, how often you repeat it, and whether you need to prove nothing was dropped. (If your files are Excel workbooks rather than CSVs, that is a slightly different job — see how to merge multiple Excel files into one sheet.)
Beginner · Works for any same-structure CSV exports.
01Merge multiple CSV files into one
Merging CSVs is an append: the rows of each file stack into one longer file, under a single header. It works cleanly only when the files share the same columns in the same meaning — weekly exports of the same report, one file per store, the same query run on different dates. The thing that separates a good merge from a messy one is not the stacking, which every method does; it is keeping exactly one header row and being able to prove the combined count adds up.
The rest of this page covers three routes — a no-install browser combine, the command line, and Power Query — and the handful of things that quietly go wrong so you can catch them.
02Merge CSV files online, without installing anything
If you would rather not open a terminal or build a query, do it in the browser. Upload the CSVs to an AI data analyst like Anomaly and ask it to combine them. Import each file (New project → Import Data → browse, or drag them in together; .csv, .xlsx and .xls up to 1GB), then ask for the merge with the checks you want.
Follow along with the three sample CSVs
Three weekly transaction files — same four columns, three rows each — that combine into one 9-row table. Synthetic data, no real customers.
"Combine a5_week1, a5_week2 and a5_week3 into one table. Match the columns, keep one header, add a source_file column, and give me the row count per file and combined, plus a check that every txn_id is unique, so I know nothing was dropped or duplicated."
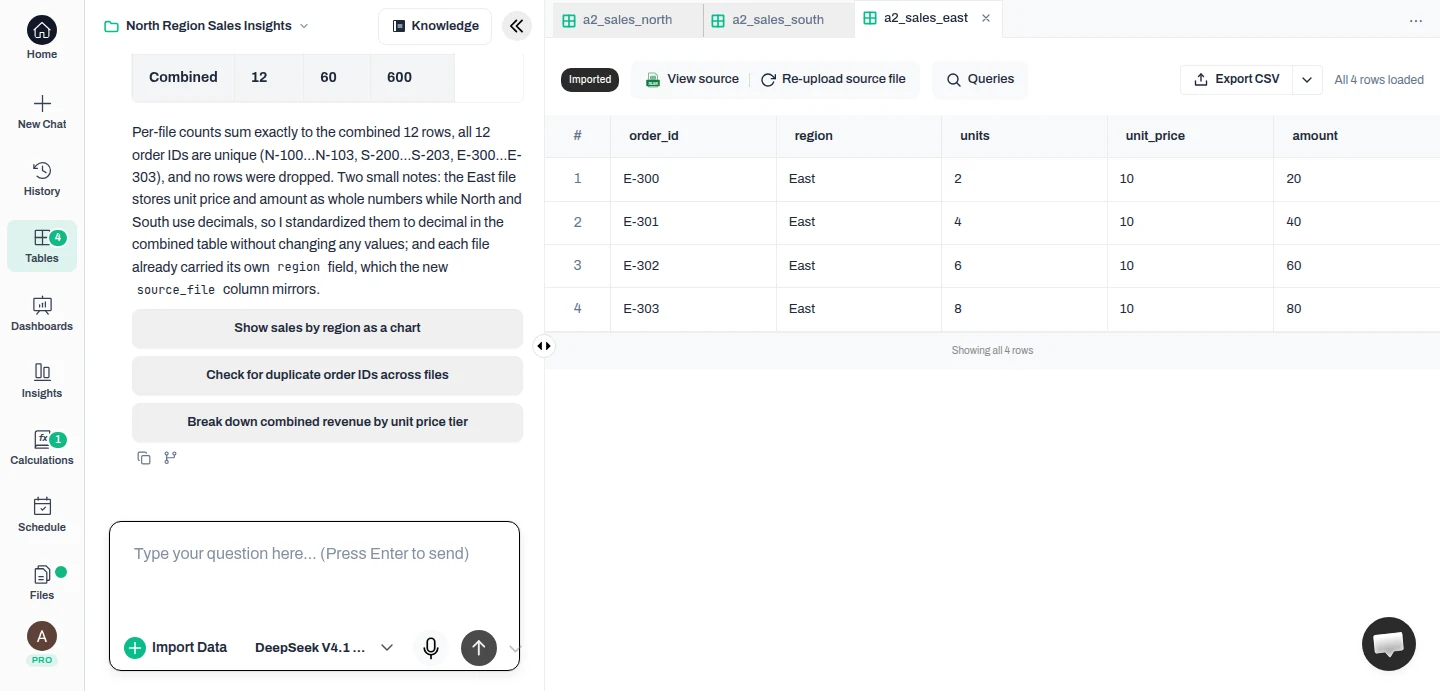
Combining CSVs in Anomaly — the three imported source files and the agent's reconciliation summary (nine transactions, matched types)
Anomaly's combine of the three sample CSVs — here the imported source files with a5_week3 open, and the agent's summary: nine transactions reconciled, column types matched across the sources, and the non-contiguous IDs flagged as source-side. In this sample run it also caught a stray repeated-header row one file's import had read as data. Synthetic example data.
Result — It stacked the three weekly files into one table with a source_file column, matched the column types across files (text stayed text, the day became a proper date, the amount a decimal), and reconciled the count so every transaction was accounted for and every id unique. It also pointed out something worth knowing: the ids are non-contiguous across files (week 1 ends at one number, week 2 starts at a higher one) — a gap that is in the source data, not rows that went missing in the merge.
That reconciliation and provenance is the difference. The combined table exports back to CSV, the combine is a step you ask for after import rather than a merge-at-upload button, and the source column and counts appear because you asked for them. The supported inputs are .csv, .xlsx and .xls up to 1GB each; on a bigger set, run the same checks and confirm the counts before you rely on the result.
03The command line and Power Query
If you are comfortable in a terminal, this is the fastest one-off. On macOS or Linux, this keeps a single header and appends the data rows from every file:
awk 'FNR>1 || NR==1' *.csv > combined.csv
That awk line assumes every record sits on one physical line and that all files share the same header, column order, and encoding — CSVs with quoted fields that span multiple lines will break it. Avoid the tempting cat *.csv > combined.csv (or copy *.csv on Windows): it copies every file whole, so the second and third headers land in the middle as data. In Python, pd.concat([pd.read_csv(f) for f in glob.glob('*.csv')]) keeps one header and aligns columns by name, but you still confirm types and encoding yourself.
For a set of files that arrives on a schedule, Excel's Power Query → Get Data → From Folder works for CSVs just as it does for workbooks: point it at the folder, combine, and refresh next time. These native routes are the right call when you can install and script; the browser combine earns its place when you cannot, or when you want the provenance and count without building them.
04What quietly goes wrong — and the checks that catch it
CSV merges fail in small, silent ways. The usual four:
Repeated headers: a naive concatenation copies every file's header row, leaving header text sitting in the middle of your data.
Different column order: if one file lists columns in a different order, a positional stack misaligns every value below it.
Encodings: mixing UTF-8 and Latin-1 files turns accented characters into garbled bytes.
Dates and numbers as text: one file quotes its dates or pads its numbers and they stop sorting or summing.
No single check catches all four — match the check to the failure. Compare per-file and combined row counts, and confirm the combined total equals the sum of the parts. Compare the header and schema across files exactly, and for any positional method (like the shell recipe) compare column order too. Spot-check a few rows for garbled characters to catch an encoding mismatch. Confirm dates and numbers parsed the same way in every file, and watch for unexpected nulls. Check that a key stays unique only when that business key is meant to be unique. When you upload and combine, you can ask for the row-count and header checks and review what it reports — in one sample run it flagged and dropped a stray repeated header and reconciled to nine rows — but run the checks that fit your files whichever method you use.
Pick the method that fits how many files you have and whether you can install anything. On macOS or Linux, the terminal one-liner awk 'FNR>1 || NR==1' *.csv > combined.csv stacks every file and keeps a single header — it assumes identical headers, column order, and encoding with one physical line per record, and is not safe for CSVs with multiline quoted fields. In Excel, Data → Get Data → From Folder appends them and re-runs on refresh. To do it in the browser with no install, and get a column recording which file each row came from plus a count you can reconcile, upload the files to an AI data analyst and ask it to combine them.
How do I merge multiple CSV files into one?
The same three routes scale from two files to many, as long as every file shares the same columns. The command line is fastest for a one-off; Power Query From Folder is best when the same set of files arrives every week or month; and an upload-and-combine is the simplest when you want a source column and a reconciled total without writing anything. All three stack the rows — none of them match on a key, which is a different job.
How do I merge CSV files online without installing anything?
Upload the files to a browser-based AI data analyst and ask it to combine them. It stacks the rows into one table, keeps a single header, standardizes the column types across files, adds a source_file column, and returns per-file and total counts so you can confirm nothing was dropped or double-counted. The combined table then exports back to CSV. Uploading is one file at a time (or several dropped in together), and the combine is a step you ask for after import.
How do I merge CSV files in Python?
With pandas: read each file and concatenate them — import pandas as pd, glob; df = pd.concat([pd.read_csv(f) for f in glob.glob("*.csv")], ignore_index=True); df.to_csv("combined.csv", index=False). That keeps one header and aligns columns by name, so a different column order is handled. What it does not do for you: read_csv infers each file's types separately and can coerce or error when they disagree, and it will not reconcile mismatched encodings — so still spot-check encoding and confirm dates and numbers parsed the same across files.
Why does my merged CSV have the header repeated in the middle?
Because a naive concatenation (cat *.csv or copy *.csv) copies every file whole, including each one's header row. The header from the second and third files ends up as data rows in the middle of the combined file. Use a method that keeps one header — the awk one-liner above, Power Query, or pandas. If you upload and combine, ask it to check for and drop any repeated header row and confirm it did; in one sample run it caught a stray header, but treat that as a check to request rather than automatic behavior.
Combine your CSVs in the browser
Upload your files, ask to combine them, and get one table with matched types, a source-file column, and counts that reconcile — no install, no script.
Ash Rai is a Technical Product Manager with 5+ years of experience building AI and data engineering products, cloud and B2B SaaS products at early- and growth-stage startups. She studied Computer Science at IIT Delhi and Computer Science at the Max Planck Institute for Informatics, and has led data, platform and AI initiatives across fintech and developer tooling.