
How to remove duplicates in Excel by key (and keep the right row)
Excel removes exact duplicate rows in a couple of clicks. The part it does not do is let you choose which row survives — the newest, or the most complete — or hand you a count you can check. This covers both: the fast native way, and the keyed way when the button is not enough.
Quick answer — how to remove duplicates in Excel
Select a cell in your data, open the Data tab, and click Remove Duplicates. Tick the columns that define a duplicate — leave them all ticked to drop rows that repeat across every column — then click OK. Excel deletes the extra rows in place and keeps the first occurrence of each. The dialog keeps whichever row sits first by position — you can nudge that by sorting, but it offers no rule for which row is best, and no reusable record of what changed. So when you need to keep the most-complete row per key and know exactly how many rows were removed, describe that rule to an AI data analyst and let it dedupe by key with a visible calculation.
Beginner·Excel for Microsoft 365, 2021, 2019 & 2016
Remove duplicates based on one column, keeping the other columns
A common need is one row per customer, per SKU, or per order — deduping on a single key column while keeping name, email, and everything else on the row. In the Remove Duplicates dialog, tick only that key column and leave the rest unticked. Excel then treats two rows as duplicates whenever the key matches, keeps the first one it meets, and drops the others along with their column values.
That word — first — is the catch. Excel keeps the topmost matching row by position, not the best row. If the first row for a customer is missing a phone number and a later row has it, the button keeps the empty one. Your only lever is sort order: sort so the row you want on top (newest date first, or non-blank values first) before you run Remove Duplicates. For a one-off cleanup that is workable; when "keep the most complete row" is the actual rule, the Remove Duplicates dialog can’t express it — you can build it with a helper column or a deterministic Power Query group-and-rank, but that is manual setup — which is the job the next section solves.
Keep the right row: first, last, or most complete
When which row survives actually matters, the rule you want is usually "one row per key, and keep the most complete one" — break ties by the newest date, then a stable final tie-breaker. Excel’s built-in dialog has no setting for that. An AI data analyst like Anomaly does: you import the file, state the rule in plain language, and it writes and runs the dedupe for you — then shows the logic and the count.
Follow along with the sample file
a1_customers_with_dupes.csv — 12 rows, keyed by email, with three emails repeated at different levels of completeness. It reproduces the run shown below. Synthetic data, no real customers.
Import the sample (New project → Import Data → drop the CSV or XLSX; uploads are supported up to 1GB). It loads as a 12-row table. Then ask for exactly the rule you want:
Remove duplicates by email, matching emails case-insensitively after trimming. Keep the most complete row (fewest empty fields, counting blank and NULL as empty); break ties by the latest signup_date, then by the lowest id. Keep every other column, and tell me exactly how many rows were removed.
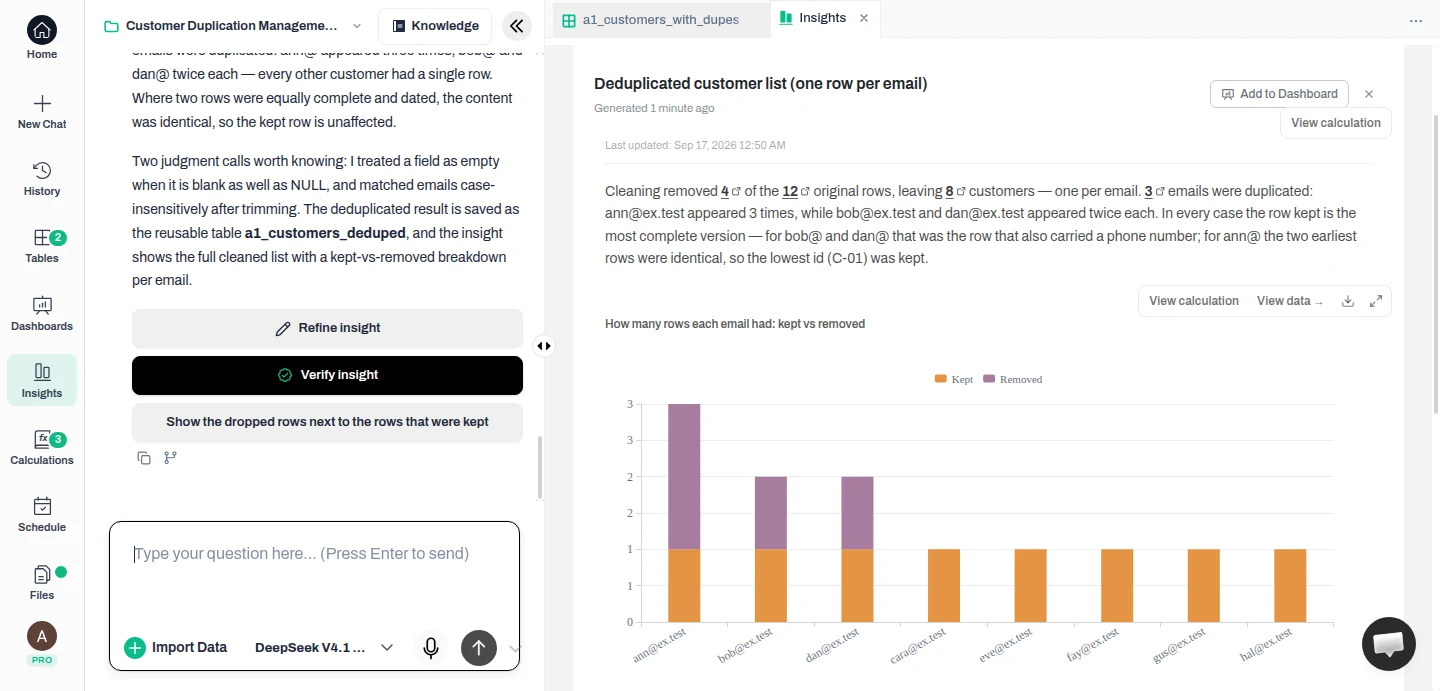
Result — On this file it removed 4 of the 12 rows and kept 8 — one per email. Three emails were duplicated:[email protected] appeared three times, [email protected] and [email protected] twice each. For bob and dan the kept row is the one that carried a phone number; ann had two rows identical on the business fields (name, email, phone, signup date) but with different ids, so the final tie-break kept the lowest id. It materializes a reusable customers_deduped table you can export, and every tile has View calculation (the exact SQL) and View data (the rows behind the number).
The advantage over the button is not speed — it is control and evidence. You choose the survivor by describing the rule (first, last, most complete, latest), the survivors keep every other column, and you get a removed count and a per-key breakdown you can audit. There is no product control that picks "which row"; you state it in words, and the same stated rule reruns on next month’s export without rebuilding it.
Before you rely on a keyed dedupe — in any tool — settle the rules the result depends on: pick the key column; decide whether to match case-insensitively and trim whitespace (the run above matched LOWER(TRIM(email))); decide what happens to blank or NULL keys so unrelated rows don’t collapse into one group; state every survivor tie-breaker so the outcome is deterministic; then reconcile the kept count against the number of distinct non-blank keys. Anomaly shows each of these in the calculation; in Excel you build and document them yourself.
Formulas and Power Query
Two more Excel routes are worth knowing, each for a different reason:
- — UNIQUE (365 / 2021):
=UNIQUE(A2:A100)spills the distinct values into a new range and refreshes as the source changes — a live unique list that leaves your data untouched, unlike Remove Duplicates. - — COUNTIF to flag:
=COUNTIF($A$2:$A2, A2)numbers each occurrence; filter for values greater than 1 to see repeats before deleting anything. - — Power Query: load the table and use Remove Duplicates for a repeatable dedupe when the duplicate rows are interchangeable. Two limits to know: it does not guarantee which duplicate instance it keeps (query folding and optimization can change execution), and its matching is case-sensitive. When the survivor matters, build a deterministic Group By that ranks the rows and keeps one — mindful that folding and buffering can affect it — rather than relying on sort order. It still shines for a step you re-run every month on a fresh export.
None of these decide "most complete" on their own — you engineer that with a ranking Group By or a helper column, and you own the case, trim, and tie-break rules. That is the manual work a stated rule removes.
Find duplicates without removing them
Often the safe first move is to see the duplicates before you delete anything. Select the column, then Home → Conditional Formatting → Highlight Cells Rules → Duplicate Values to colour every repeated value. To count instead of colour, add the COUNTIF helper column from above and read anything above 1 as a repeat. Review what is actually duplicated — sometimes two rows share a name but not a customer — then remove with the method that fits.
Check your result
Deletes are easy to get wrong quietly. Note the row count before you start (select the column and read the count on the status bar), then confirm the after-count equals the number of distinct keys you expected. Keep the removed rows somewhere — a filtered copy, or a separate sheet — so the change is auditable rather than gone. When you dedupe by key in Anomaly, that check is built in: it reports the removed count, keeps a kept-vs-removed breakdown per key, and can show the dropped rows next to the ones it kept, so the number is one you can defend.
Related: for the broader set of Excel cleanup and analysis techniques, see Excel data analysis: formulas, PivotTables & charts. Removing duplicates while combining several files, or comparing two lists for the differences, are separate jobs from this one.
FAQ
How do I remove duplicates in Excel?
Click any cell in your data, open the Data tab, and choose Remove Duplicates. In the dialog, tick the columns that define a duplicate — leave all ticked to drop rows that repeat across every column — then click OK. Excel deletes the extra rows in place and reports how many it removed. It always keeps the first occurrence of each duplicate; you can influence which row that is only by sorting first, not by a rule such as "keep the most complete row".
How do you remove duplicates in Excel based on one column?
Open Data → Remove Duplicates and tick only that one column, leaving the others unticked. Excel then treats two rows as duplicates whenever that column matches and keeps the first one it finds, discarding the rest — including the other columns on those rows. Because it keeps the topmost row by position, sort the sheet first if you care which row is kept (for example, newest date on top). When "first by position" is not the rule you want — you want the most-complete row, or a counted, auditable result — describe the rule in words to an AI data analyst instead.
How do I remove duplicates in an Excel column?
To collapse a single column to its unique values, either use Data → Remove Duplicates with only that column ticked, or, in Excel 365 and 2021, write =UNIQUE(range) in an empty column to spill the distinct values without touching the original. UNIQUE updates automatically as the source changes; Remove Duplicates is a one-time edit of the data itself.
Does Remove Duplicates keep the first or last row?
Excel keeps the first occurrence — the topmost matching row — and removes the ones below it. There is no built-in option to keep the last row or the most-complete row. To keep the last, sort so the row you want is on top before you run Remove Duplicates. To keep the most-complete row per key regardless of position, you need a rule the built-in dialog cannot express — you would build it with a helper column or a deterministic Power Query group-and-rank; a natural-language dedupe by key handles it and shows the exact logic it used.
How do I find duplicates in Excel without removing them?
Select the column, then Home → Conditional Formatting → Highlight Cells Rules → Duplicate Values to colour every repeated value. To count them, add a helper column with =COUNTIF($A$2:$A2, A2) and read any result greater than 1 as a repeat. This flags duplicates so you can review them before deciding what to delete.
What is the fastest way — is there a shortcut?
In Excel for Windows with a US/English keyboard layout, press Alt, then A, then M — the ribbon KeyTips that open Data → Remove Duplicates without the mouse (other platforms and layouts use different keys). There is no single hotkey that removes duplicates outright, because Excel needs you to confirm which columns define a duplicate first.
Dedupe by key without writing the formula
Import your file, describe the rule for which row to keep, and get a cleaned table, an audited removed count, and the exact calculation behind it — nothing to wire up in Excel.